
AI systems that show their work and refuse to fake it
 Rohit Agrawal — principal engineer. From understanding the requirement to what's actually running in production — and feeding what I learn back into the next release. Fourteen years deciding whether software was safe to release; now I build AI systems that make that decision about themselves.
- Experience
- 14+ yrs — Oracle, Amazon, LimeRoad, Mobileum, Snapdeal, Subex
- Most recent
- Oracle Principal MTS · 2019–2026
- Since April 2026
- Building independent AI systems, full time
- Led
- 11+ quality engineers and SDETs, globally
- Seeking
- Senior / Principal — AI platform engineering, LLMOps, forward-deployed AI · AI quality engineering, test automation and agentic AI
Fourteen years I can tell you about. Six practices you can check yourself.
The last row is the one that costs me something. It stays.
Two ledgers, deliberately kept apart.
Employer outcomes are reported and marked approximate; the independent systems are evidence you can inspect. The two are never averaged into a single number.
Employer outcomes
- Manual test design
- ~40% less effort
- Automation coverage
- 65% → 95%
- Production incidents
- ~20% fewer
- Payment defects in production
- ~25% fewer
- Release validation
- ~35% less manual effort
Independent StackClimb systems
StackClimb is where Rohit Agrawal builds independent AI systems — outside any employer.
- CiteVyn
- Answers only what it can cite, and refuses the rest.
- Quorum-AI
- Four models answer; a moderated critique maps their disagreement.
- SaafSaans
- Your air, not the city average — readings labelled live, cached, or no reading.
- NarraTwin AI
- Cited walkthroughs; every claim is checked against its source.
- EvalAxis
- A regression gate that fails the build when quality drops — private, in progress.
What you can use, and what is still being built
Use them now
- CiteVynLive — cold-startsAnswers from official docs and shows its sources — or says it can’t.Golden suite — 52 / 52 cases
- Quorum‑AILiveAsks four AI models the same question and shows where they disagree.Coverage floor — 88%, enforced in config
- SaafSaansDeployed — sleeps when idleScores your air risk for today — yours, not the city average.Feeds — 19 live · 2 known gaps
Being built
- Aegis ContractsIn progress · closedRules for what one AI system may promise another.
- EvalAxisIn progress · closedBlocks a release when answer quality drops, the way a failing test would.12,978 lines · 388 test functions
- NarraTwin AIPhase 1 — No-GoTurns project knowledge into cited walkthroughs; its own gate says not yet.Surface parity — 25 / 25 agree
CiteVyn
“Can I trust this answer — and trace every claim to its source?”
Citation-grounded Q&A over official AI documentation. Answers quote their sources verbatim; where no source supports an answer, CiteVyn refuses instead of guessing. Index updates reach production only through an evaluation gate.
Twenty-six answerable questions. It found the right source for every one.
GateA 15-case retrieval suite on the candidate index gates promotion; any override is audited

Committed visual baseline, citevyn at df8cfc3. Both citations are real documentation URLs.
- Not claimed
- Corpus scale · adoption · SLA
Quorum‑AI
“What happens when four models disagree about your question?”
One question runs against four models in parallel. A separate moderator pass — its own call, with its own configured model — reads all four answers and critiques them over two rounds; a round dropped for time is recorded as skipped, not hidden. The four never read each other. A synthesis then returns consensus, disagreement, source support, uncertainty, and a recommendation.
Disagreement and uncertainty come back as their own fields, not folded into one confident answer.
GateCost approved before anything runs; fallbacks disclosed
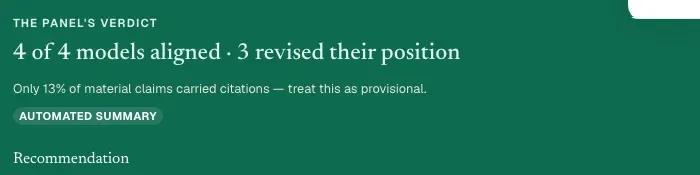
SAMPLE — an end-to-end acceptance fixture rendering canned data (e2e/fixtures/golden-run.ts), not a measured run. Live execution is off by default. The revision count is inferred from position movement, and the interface says so.
- Not claimed
- Latency · accuracy · adoption
SaafSaans
“Is it safe for me to go outside right now — and if not, when?”
A Delhi-NCR air-quality companion that scores your risk — age, condition, planned activity — rather than the city’s average, across a repo-stated 21 stations, and answers questions with cited health guidance. The Hindi draft ships behind a banner saying no Hindi speaker has reviewed it yet.
Two people, one sky. The adult with asthma scores 76. The healthy adult, same plans, scores 64.
RuleEvery reading labelled live, cached, or no reading
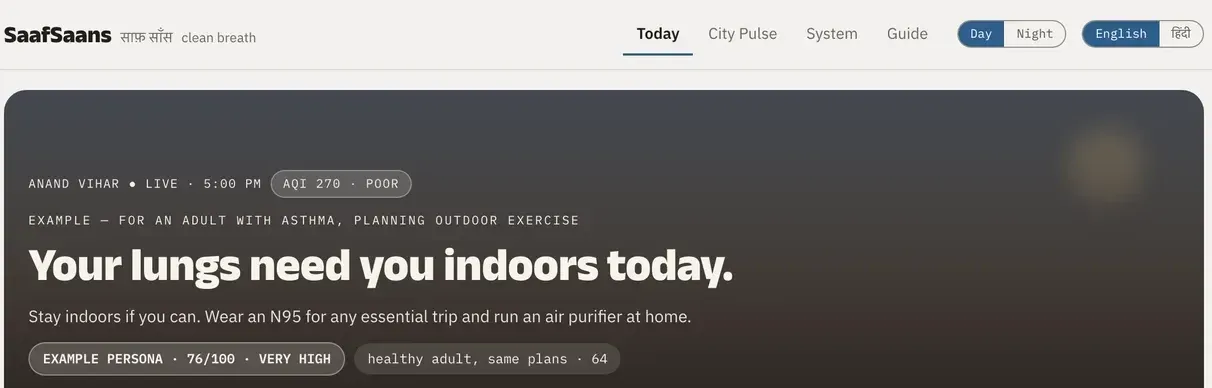
Captured live 11 Aug 2026, 5:00 PM. Cropped above a time-window strip showing a defect under repair.
- Not claimed
- Medical advice · uptime
NarraTwin AI
“Can project knowledge become a walkthrough without inventing a claim?”
Grounded walkthrough generation with citations, claim evaluation, consent checks, and release gates that run before anything is generated. Its own release-readiness review currently reads No-Go — so it is not deployed, and this page says so.
Twenty-five languages, six script classes. Every one proved to agree across five surfaces against a pinned fixture.
GateIts own readiness review says No-Go, so it is not deployed
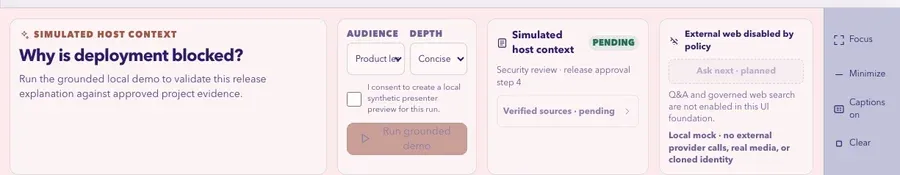
SAMPLE — interface design, not a running capture. No screenshot of the built system exists yet, so this stands in and is labelled rather than implied.
- Not claimed
- Deployment · video · avatar Q&A
Carried, not shown
Two systems are still being built. They stay closed until they can be judged on finished work rather than on intent. They are named because a record that discloses its gaps should also say what exists, and the question each one is built to answer costs nothing to state.
EvalAxis
“Why can a failing test stop a release, when a measured drop in answer quality cannot?”
Evaluates LLM, RAG, and agent changes with evidence, and blocks CI on a quality regression.
In progress · closedAegis Contracts
“What should one AI system be allowed to promise another — and who checks?”
Early-stage work on contract-shaped guarantees between AI systems.
In progress · closedOne message away
Open to senior and principal roles in AI platform engineering, LLMOps and forward-deployed AI, and to AI quality engineering, test automation and agentic AI leadership. Fourteen years of evaluation and release governance sits underneath all of them.
- Based
- Bengaluru, India · IST (UTC+5:30)
- Open to
- Relocation worldwide · international travel
- Work authorisation
- India · United States — H-1B approved